
This article is a guided first run of place and route in ChipVerify Lab. You take the 8-bit counter from RTL through synthesis and the full OpenROAD flow, then read every section of the report: area and floorplan, timing, clock tree, power, IR drop and the checks. Along the way you will see which numbers change between synthesis and layout, and what the two settings of the PnR panel, the clock period and the utilization, actually do.
9 min read | Beginner
What You'll Learn
- Run synthesis and place and route in ChipVerify Lab
- Explain what the clock period and core utilization settings control
- Read the area, timing, CTS, power and IR drop sections of a PnR report
- Compare post-layout results with the synthesis estimates
Step 1: Synthesize
Open the example (link at the end of this article). The design is the counter from The RTL-to-GDSII Flow. In the synthesis panel, keep the hd library and the typical corner, and run synthesis. The result:
| Cell | Count | Area (um2) |
|---|---|---|
| dfxtp_1 (flip-flop) | 8 | 160.15 |
| a21oi_1, o21a_1, nor3_1, and3_1, and4_1, a41oi_1, nor2_1 | 20 | 120.11 |
| Total | 28 | 280.27 |
The flip-flops take 57 % of the area: a dfxtp_1 is 7.36 um wide, more than five inverters.
Step 2: Set Up Place and Route
The PnR tab has two main settings:
- Clock Period: the target for the clock
clk, here 5 ns (200 MHz). The flow creates the clock withcreate_clock, gives every input and output a delay of 20 % of the period, builds the clock tree and repairs setup and hold timing against it. - Core Utilization: how full the core should be, here 50 %. The flow sizes the floorplan for this value (up to 75 %) and sets the placement density a little above the real core utilization. Very small designs, under 20 cells, get a fixed 60 um die instead.
The library and corner are taken from the synthesis run. PRO users can also set a die area, use TinyTapeout mode, change advanced options such as the aspect ratio, the pin sides or the I/O delay, or edit the OpenROAD script directly.
Step 3: Run and Read the Report
Click Run Place & Route. The counter finishes in well under a minute. Here is what each section shows for this run, and what it means.
Area and Floorplan
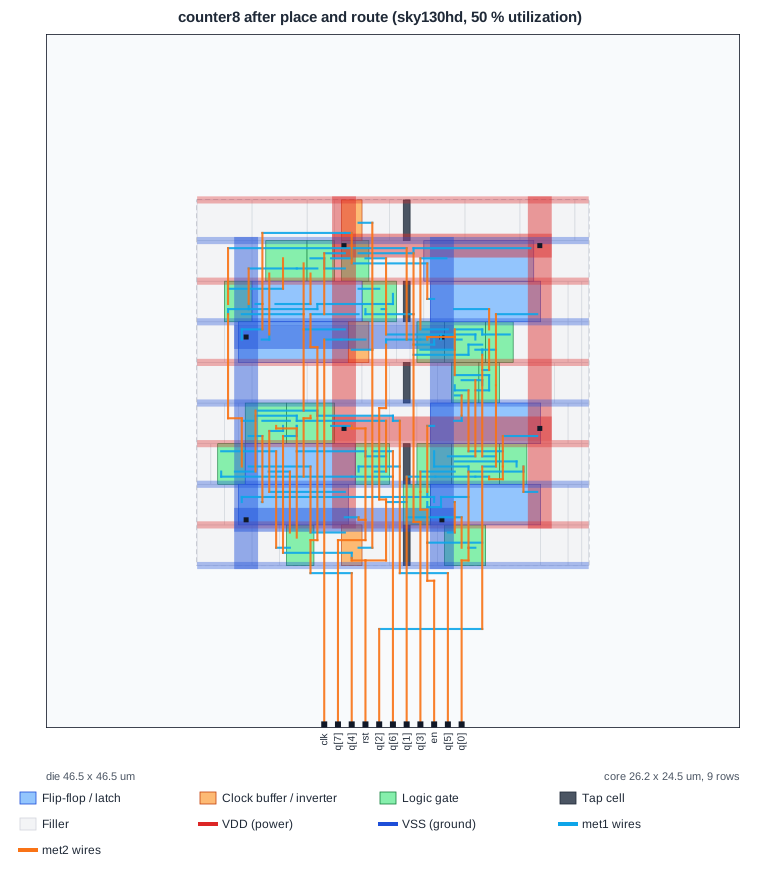
The design area is 302 um2 at 59 % utilization. The extra 22 um2 over synthesis are three clock buffers and five tap cells. The core is 23.5 um by 21.8 um with 8 rows, and the die, with a 10 um margin for the pins, is 43.7 um square. All 11 pins ended up on the left edge; I/O Pin Placement explains how the pin placer decides.
Static Timing (Post-Route)
The worst setup path starts at the input en and runs through an and4_1, two and3_1 and an o21a_1 to flip-flop _47_, the carry chain of the counter:
  1.0000 v input external delay
  1.0000 v en (in)
  1.1706 v _21_/X (sky130_fd_sc_hd__and4_1)
  1.4277 v _22_/X (sky130_fd_sc_hd__and3_1)
  1.6478 v _23_/X (sky130_fd_sc_hd__and3_1)
  1.8131 v _39_/X (sky130_fd_sc_hd__o21a_1)
  1.8132   data arrival time
  5.1203   data required time
  3.3071   slack (MET)
Three things are new compared with synthesis timing. The input en is assumed to arrive 1 ns, 20 % of the period, after the clock edge, so paths from the inputs start late. The capturing flip-flop gets its clock through the clock tree, 0.22 ns after the clock pin. And the timing uses the capacitance and resistance extracted from the routed wires, so each gate is a little slower than with ideal wires. With 3.31 ns of slack, this design could run much faster.
CTS
The clock tree has 8 sinks (the flip-flops) and 3 buffers, all clkbuf_2: one root and two leaves, each leaf driving four flip-flops. The path depth is 2 buffers to every flip-flop, which keeps the skew small: the report shows 0.22 ns of insertion delay and no measurable skew. See CTS in OpenROAD.
Power
Group                  Internal  Switching    Leakage      Total
Sequential             6.50e-05   1.29e-06   6.49e-11   6.63e-05  63.2%
Combinational          1.59e-06   1.05e-06   4.58e-11   2.63e-06   2.5%
Clock                  1.64e-05   1.96e-05   1.25e-11   3.59e-05  34.3%
Total                  8.30e-05   2.19e-05   1.23e-10   1.05e-04 100.0%
The total is 105 uW at 200 MHz with the default switching activity. The flip-flops and the clock network use 97 % of it: they toggle on every clock edge, while the counter logic switches far less. Leakage is negligible at the typical corner.
IR Drop
The IR drop analysis solves the resistance of the power grid with the current drawn by every cell. For the counter, the worst drop is 1.94e-05 V on VDD and 2.61e-05 V on VSS, against a 1.80 V supply: about 0.001 %. A design this small hardly loads the grid. The block has no power pins of its own, so the analysis assumes a grid of supply bumps above it. The IR Drop article shows a design where it matters.
Antenna, DRC and LVS
The antenna check finds 0 net and 0 pin violations, and the detailed router reports no routing violations. The DRC section (KLayout) then checks the GDSII against the full manufacturing rules and finds 0 violations. The LVS section compares the transistors extracted from the GDSII with the routed netlist: 31 devices and 36 nets on both sides, a match. DRC and LVS explain both checks.
Quick Check
Q: The report says 59 % utilization, but the PnR panel was set to 50 %. Is something wrong?
Show Answer
No. The floorplan was sized for 50 % of the synthesized cell area, and snapping the core to whole rows and sites made it slightly smaller. The 59 % is the final cell area, including the clock buffers and tap cells, over that core. The panel value sizes the floorplan; it is not a promise about the final number.
Step 4: Push the Clock
With 3.31 ns of slack at 5 ns, the critical path takes about 1.7 ns, but 1 ns of it is the assumed input delay, which shrinks with the period. The clock section of the report gives the fastest clock for the paths between flip-flops: 1.35 ns. What happens at 1.5 ns and 1.2 ns?
- 1.5 ns: the flow finds no setup violation during placement, and the routed design has +0.15 ns of slack. The layout is the same as at 5 ns.
- 1.2 ns: after CTS,
repair_timingfinds 3 failing endpoints and upsizes 5 cells. It reaches +0.005 ns with wires estimated from the placement, and the area grows to 312 um2. After routing, the estimate from the global routes says -0.08 ns, but the timing with the extracted wires gives +0.0015 ns: met by 1.5 picoseconds.
Quick Check
Q: At 1.2 ns, the estimate after routing says the design fails, but the final timing says it passes. Which one counts, and why do they differ?
Show Answer
The final timing counts, because it uses the resistance and capacitance extracted from the real wires. The estimates multiply wire lengths by average values per layer, which can be off by several percent in either direction. With only picoseconds of margin, that is enough to flip the verdict, which is why sign-off always uses extraction.
Running It in ChipVerify Lab
The example is the counter. Synthesize it, run Place and Route at 5 ns and 50 %, and check your numbers against this article. Then try the clock periods of Step 4.
Common Mistakes
Mistake #1: Running PnR before the synthesis result is clean
Check the synthesis log for warnings, latches and unexpected cells first. A problem in the netlist is much harder to spot in a layout.
Mistake #2: Judging timing from the pre-route repair log
The repair step reports slack with estimated wires. Always read the post-route timing section; it is the result that counts.
Mistake #3: Setting utilization very high on a tiny design
On a small design, a high utilization leaves very few rows and little routing space. Keep the default until you have a reason to change it, and see the utilization sweep for what happens when you push it.
Practice Exercise
Challenge: Find the Fastest Clock
Run Place and Route at 1.5 ns, 1.2 ns and 1.1 ns. Record the worst setup slack, the design area, and whether any cells were resized. At which period does the routed counter stop meeting timing?
Hint
Look at the post-route timing section, and search the log for "Resized".
Solution
At 1.5 ns: slack +0.15 ns, 302 um2, no resizing. At 1.2 ns: the repair step upsizes 5 cells (area 312 um2), and the routed slack is +0.0015 ns. At 1.1 ns: the repair upsizes 7 cells and adds a buffer (325 um2) but stops at -0.055 ns, and the routed slack is -0.06 ns. The limit lies between 1.1 and 1.2 ns.
Open the ready-made example in the lab, synthesize it and run Place and Route.
Summary
- In the lab, synthesize first, then run Place and Route with a clock period and a core utilization.
- The report covers area and floorplan, post-route timing, CTS, power, IR drop, antenna, DRC and LVS.
- The counter: 302 um2, 59 % utilization, +3.31 ns slack at 5 ns, 3 clock buffers, 105 uW, clean DRC and LVS.
- Timing repair during placement uses estimated wires; only the post-route timing with extracted wires is final.
