
ASIC design flow is the systematic methodology for transforming a chip concept from initial requirements through architecture, RTL design, verification, synthesis, physical implementation, and validation--a multi-stage process used by semiconductor companies to develop custom integrated circuits for applications ranging from smartphones to data centers.
15 min read | Beginner to Intermediate
What You'll Learn
- The complete ASIC design flow from requirements gathering through post-silicon validation
- How RTL design, verification, and synthesis transform HDL code into physical chips
- The roles of different engineering teams (architects, designers, verification, physical design) in chip development
- Industry practices used by companies like Intel, NVIDIA, and Qualcomm to develop modern processors
What is VLSI?
VLSI stands for Very Large Scale Integration, a technology used to create integrated circuits (ICs) by combining millions or billions of transistors into a single chip. VLSI technology revolutionized electronics by enabling compact, powerful, and cost-effective microprocessors, memory chips, digital signal processors, and advanced electronic devices.
Modern VLSI processes operate at nanometer-scale nodes. As of 2024, leading-edge processes have reached 3nm technology nodes, with feature sizes enabling the integration of tens of billions of transistors on a single chip. Companies like TSMC, Samsung, and Intel manufacture processors using 5nm, 3nm, and emerging 2nm process nodes, delivering unprecedented performance and power efficiency.
Real-World Application
Apple M3 Processor: Apple's M3 processor, manufactured on TSMC's 3nm process, integrates over 25 billion transistors on a single die. This includes CPU cores, GPU cores, neural engine, memory controllers, and I/O interfaces--demonstrating the massive integration density enabled by modern VLSI technology.
What is an ASIC?
An ASIC (Application-Specific Integrated Circuit) is an integrated circuit designed to perform a specific task or function, unlike general-purpose ICs such as microprocessors and memory chips. ASICs are customized for particular applications where specialized processing delivers superior performance, power efficiency, or cost advantages compared to programmable alternatives.
ASICs are used in high-performance applications including:
- Cryptocurrency mining: Bitcoin ASICs perform SHA-256 hashing
- Networking: Packet processing and routing ASICs in data center switches
- AI acceleration: Google's TPU and NVIDIA's tensor cores for machine learning
- Consumer electronics: Custom chips in smartphones, cameras, and IoT devices
- Automotive: Safety-critical ASICs for ADAS (Advanced Driver Assistance Systems)
ASICs offer better performance and power efficiency than FPGAs or software solutions for fixed functions, but require high upfront development costs (NRE - Non-Recurring Engineering). Choose ASICs when production volumes justify the investment.
ASIC Design Flow Overview
A typical ASIC design flow follows a structured methodology broken down into multiple stages. Some phases happen in parallel (e.g., design and verification), while others are sequential (e.g., synthesis must follow RTL design). The complete flow from concept to silicon typically takes 12-24 months for complex SoCs.
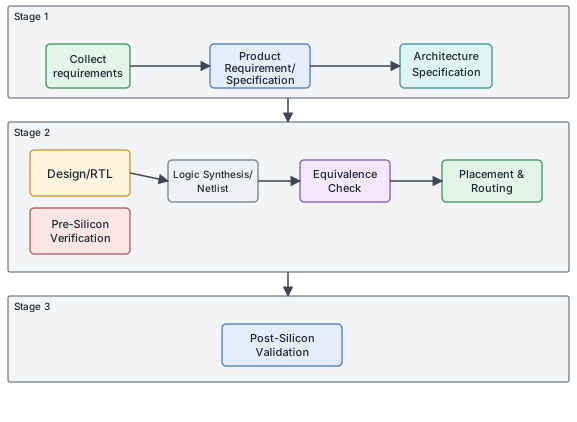
The flow consists of three major stages: (1) Specification and Architecture, (2) Implementation and Verification, and (3) Fabrication and Validation. Each stage involves specialized teams with distinct skill sets.
Stage 1: Specification and Architecture
Requirements Gathering
A semiconductor company's customer is typically another company that will integrate the chip into their systems or products. Requirements gathering involves understanding customer needs, estimating market value, evaluating resources, and defining success criteria.
Key activities include:
- Market analysis and competitive benchmarking
- Performance targets (performance, power, area - the "PPA triangle")
- Cost constraints and target selling price
- Time-to-market requirements and schedule risk assessment
- Regulatory and compliance requirements (automotive safety, medical certification, etc.)
Specifications
Specifications abstractly describe the functionality, interfaces, and overall architecture of the chip. This document serves as the contract between stakeholders and guides all subsequent design work.
Example specifications for a mobile application processor:
- Requires computational power to run imaging algorithms supporting 4K video at 60 FPS
- Requires four ARM Cortex-A78 high-performance cores and four ARM Cortex-A55 efficiency cores with coherent interconnect, running at 2.4 GHz and 1.8 GHz respectively
- Requires USB 3.2, Bluetooth 5.3, Wi-Fi 6E, and PCIe Gen 4 interfaces
- Should support 4K HDR display (3840x2160) with dedicated display controller
- Must include ISP (Image Signal Processor) supporting 200MP camera sensors
- Power budget: 5W TDP (Thermal Design Power) for sustained workloads
Incomplete or ambiguous specifications are the leading cause of design respins. Invest time upfront to precisely define interfaces, performance metrics, and corner case behavior to avoid costly redesigns later.
Architecture
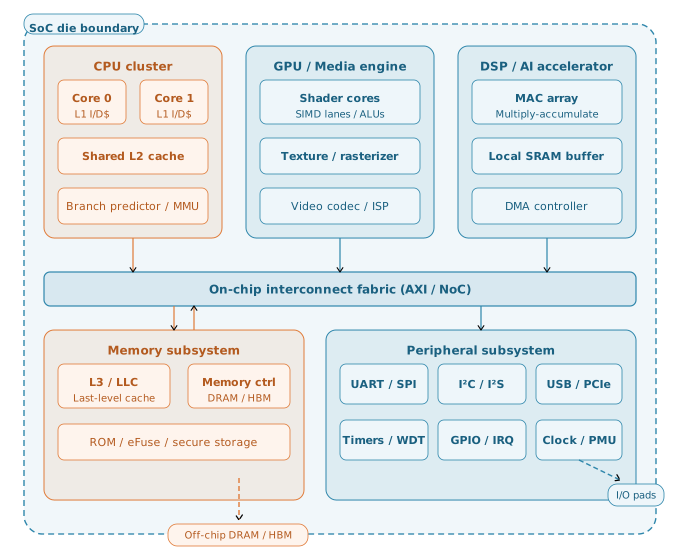
System architects develop a high-level view of chip operation, deciding component selection, clock frequencies, power domains, data flow, and how to meet PPA (Performance, Power, Area) targets.
Architectural decisions include:
- Processing elements: CPU core selection, GPU architecture, accelerators (NPU, DSP)
- Memory hierarchy: Cache sizes (L1, L2, L3), DRAM interface (LPDDR5, DDR5), on-chip SRAM
- Interconnect: Bus topology (AXI, CHI), network-on-chip (NoC) for complex SoCs
- Clock domains: Multiple clock regions with CDC (Clock Domain Crossing) management
- Power management: Voltage/frequency scaling, power gating, retention strategies
Real-World Application
Qualcomm Snapdragon Architecture: Qualcomm's Snapdragon 8 Gen 3 architecture team decided on a 1+5+2 CPU cluster (1 Cortex-X4 prime core at 3.3GHz, 5 Cortex-A720 performance cores, 2 Cortex-A520 efficiency cores), Adreno 750 GPU, Hexagon NPU for AI, and custom ISP. This heterogeneous architecture balances peak performance with battery life--architectural decisions driven by smartphone use cases.
Stage 2: Implementation and Verification
Digital Design (RTL Development)
Because modern chips integrate billions of transistors, building from scratch is impractical. Design teams reuse IP (Intellectual Property) blocks and develop new components using Hardware Description Languages (HDL) like Verilog and SystemVerilog.
For example, a company requiring a FlexCAN module for automotive applications can either:
- License the IP from a vendor (e.g., Synopsys DesignWare, Cadence, ARM)
- Develop custom IP in-house using HDL
RTL (Register Transfer Level) design describes circuit behavior at a high abstraction level, focusing on data flow between registers and combinational logic rather than individual transistors.
Example: Single-Port RAM in Verilog
module ram_single_port
#(
 parameter ADDR_WIDTH = 16, // 64K addresses
 parameter DATA_WIDTH = 32 // 32-bit data bus
)
(
 input wire clk, // Clock input
 input wire we, // Write enable (1=write, 0=read)
 input wire [ADDR_WIDTH-1:0] addr, // Address input
 input wire [DATA_WIDTH-1:0] din, // Data input (for writes)
 output wire [DATA_WIDTH-1:0] dout // Data output (for reads)
);

 // Memory array: 2^16 locations, each 32 bits wide
 reg [DATA_WIDTH-1:0] mem [2**ADDR_WIDTH-1:0];

 // Synchronous write operation
 always @(posedge clk) begin
 if (we == 1'b1)
 mem[addr] <= din; // Write data to address 'addr' on clock edge
 end

 // Asynchronous read operation (combinational)
 assign dout = mem[addr]; // Read data from current address

endmodule
This RTL describes memory behavior without specifying how it synthesizes to hardware. Synthesis tools will infer SRAM blocks, registers, or compile to flip-flops depending on the target technology.
Parameterized RTL (using parameter) creates reusable IP blocks that can be configured for different widths and depths. This is standard practice in commercial IP development--write once, instantiate with different configurations.
Verification
Once RTL design is ready, it must be verified for functional correctness. For example, how do we ensure a DSP processor correctly fetches instructions from memory and executes them?
Functional verification uses EDA simulators (Synopsys VCS, Cadence Xcelium, Siemens Questa) to model the design and apply stimulus. This is the domain of pre-silicon verification engineers who develop testbenches using SystemVerilog, UVM (Universal Verification Methodology), and formal verification tools.

To accelerate time-to-market, design and verification teams work in parallel:
- Design team releases an RTL version (e.g., v1.0)
- Verification team develops testbench environment and test cases for that RTL version
- If tests fail, verification files a bug report with specific reproduction steps
- Design team fixes the bug in the next RTL release (e.g., v1.1)
- Process iterates until functional coverage goals are met (typically 95-99% coverage)
Real-World Application
Intel CPU Verification: Intel's CPU verification teams spend 2-3x more engineering effort on verification than design. A modern Intel processor undergoes billions of simulation cycles across thousands of test scenarios (random instruction sequences, corner case stress tests, real workloads). Verification coverage metrics track which RTL lines, FSM states, and cross-product scenarios have been exercised, ensuring no untested code reaches silicon.
Verification is the most time-consuming phase in ASIC design flow. Industry data shows 60-70% of project effort goes to verification. Budget schedule and resources accordingly.
Logic Synthesis
Synthesis converts RTL HDL code into a gate-level netlist--a description of the circuit using standard cells (NAND, NOR, flip-flops, multiplexers) from a technology library.
Synthesis tools (Synopsys Design Compiler, Cadence Genus) perform:
- Translation: Convert HDL to generic boolean logic
- Optimization: Minimize area, meet timing constraints, reduce power
- Mapping: Map logic to standard cells from the technology library (e.g., TSMC 5nm library)
Example: Gate-Level Netlist
// Synthesized netlist from RTL (partial example)
and_2_0 u_and2_0 (
 .in_a (_net_112), // Input A connected to net 112
 .in_b (_net_56), // Input B connected to net 56
 .out (_net_222) // Output connected to net 222
);

ff_lt u_ff_lt_122 (
 .d (_net_222), // Data input from AND gate output
 .clk (_net_11), // Clock signal
 .q (_net_76) // Flip-flop output
);
The netlist specifies exact cell instances (e.g., and_2_0 is a 2-input AND gate from the standard cell library) and net connections. Technology libraries from fabs (TSMC, Samsung, Intel) provide timing characteristics: rise/fall times, propagation delays, capacitance, leakage current.
Synthesis tools optimize for PPA:
- Performance: Meet clock frequency targets (e.g., 3.0 GHz) by minimizing critical path delay
- Power: Reduce dynamic power (switching activity) and static power (leakage)
- Area: Minimize die size to reduce manufacturing cost
Logic Equivalence Checking (LEC)
After synthesis, the gate-level netlist must be proven functionally equivalent to the RTL. Equivalence checking tools (Synopsys Formality, Cadence Conformal) mathematically verify that synthesis didn't introduce bugs.
LEC is essential because:
- Synthesis optimizations can inadvertently change functionality
- Gate-level simulation is 10-100x slower than RTL, so full regression testing is impractical
- Catching synthesis bugs early prevents costly respins
Some projects also perform gate-level verification where critical paths or timing-sensitive logic are re-verified with back-annotated delays from synthesis, but this is slower due to increased netlist complexity.
Placement and Routing (Physical Design)
The gate-level netlist feeds into the physical design flow, where automatic Place and Route (APR or PnR) tools create the physical layout that will be manufactured.
Physical design tools (Cadence Innovus, Synopsys IC Compiler II) perform:
- Floorplanning: Define chip dimensions, power grid, macro placement (RAM, ROM blocks)
- Placement: Position standard cells in rows, optimizing for timing and congestion
- Clock Tree Synthesis (CTS): Build balanced clock distribution network with minimal skew
- Routing: Connect cells using metal layers (modern processes have 10-15 metal layers)
- Timing Optimization: Insert buffers, resize gates, optimize paths to meet timing closure
- Physical Verification: DRC (Design Rule Check), LVS (Layout vs Schematic), antenna checks
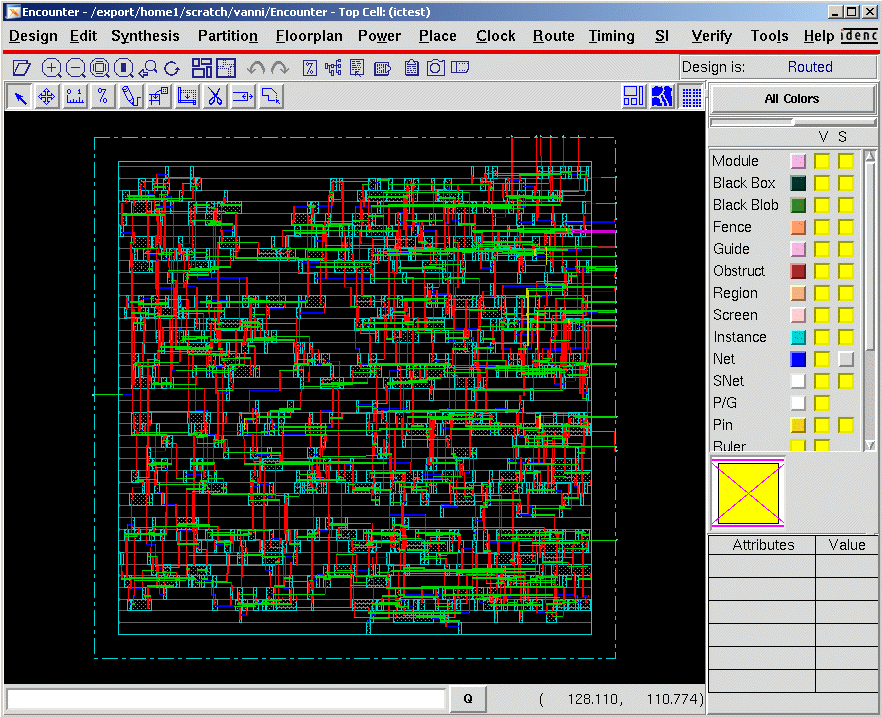
The output is a GDSII file--the final layout database sent to the foundry for mask generation and fabrication.
Real-World Application
NVIDIA GPU Physical Design: NVIDIA's H100 GPU manufactured on TSMC 4N process contains over 80 billion transistors on an 814mm² die. The physical design team managed clock distribution to thousands of clock domains, power delivery across hundreds of amperes, and thermal hotspots using advanced packaging (CoWoS - Chip-on-Wafer-on-Substrate). Achieving timing closure at its target clock frequency required months of iterative optimization.
Stage 3: Fabrication and Validation
Fabrication
The GDSII layout is sent to a semiconductor foundry (TSMC, Samsung Foundry, GlobalFoundries, or internal fabs like Intel's) for manufacturing. The foundry uses photolithography to pattern silicon wafers through hundreds of process steps over 2-3 months.
Fabrication involves:
- Wafer preparation and oxidation
- Photolithography using EUV (Extreme Ultraviolet) or DUV (Deep Ultraviolet) for sub-7nm nodes
- Etching, doping, and deposition of metal layers
- Wafer testing and dicing into individual dies
- Packaging and final test
Post-Silicon Validation
After fabrication, sample chips undergo post-silicon validation where engineers run test patterns on actual silicon using automated test equipment (ATE) and specialized validation boards.
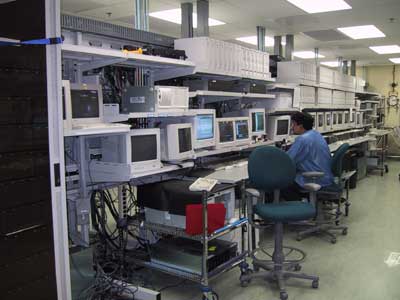
Post-silicon validation is significantly more challenging than pre-silicon verification:
- Limited visibility: Cannot probe internal nodes; rely on scan chains and built-in self-test (BIST)
- Speed: Billions of cycles execute per second; tracing back to the exact error cycle is difficult
- Cost: Each silicon iteration costs millions of dollars; bugs must be found quickly
- Real-world variability: PVT (Process, Voltage, Temperature) variations affect behavior
If bugs are discovered in post-silicon:
- Critical bugs require RTL fixes and a full respin (tape-out again, adding 3-6 months)
- Minor bugs may be worked around in firmware or via metal-only ECO (Engineering Change Order) fixes
- All fixes must be re-verified and physical design updated
Silicon respins are extremely expensive (>$10M for advanced nodes) and delay time-to-market. Invest in thorough pre-silicon verification to catch bugs before tape-out.
Real-World Application
Intel Pentium FDIV Bug (1994): A famous post-silicon bug: Intel's Pentium processor had a floating-point division error affecting 1 in 9 billion operations. While rare, the bug required a recall costing Intel $475 million. This case study emphasizes the importance of exhaustive verification--even corner cases with low probability must be tested.
Team Roles in ASIC Design
ASIC development requires collaboration across specialized teams:
| Role | Responsibilities | Skills Required |
|---|---|---|
| System Architect | Define high-level architecture, PPA targets, component selection | Computer architecture, performance modeling, power analysis |
| RTL Designer | Write synthesizable Verilog/SystemVerilog RTL code | HDL coding, digital design, synthesis-aware coding |
| Verification Engineer | Develop testbenches, write test cases, achieve coverage goals | SystemVerilog, UVM, scripting (Python, Perl), formal methods |
| Synthesis Engineer | Run synthesis, meet timing/power/area constraints | Synthesis tools, timing analysis, constraint writing (SDC) |
| Physical Design Engineer | Floorplanning, P&R, timing closure, physical verification | APR tools, STA (Static Timing Analysis), DRC/LVS, clock tree synthesis |
| Post-Silicon Validation Engineer | Test silicon samples, debug hardware issues, characterize PVT corners | Hardware debugging, ATE programming, lab equipment, signal integrity |
Common Beginner Mistakes
Mistake #1: Underestimating Verification Effort
Why it's problematic: New teams often allocate 50/50 design-to-verification effort, but industry best practice is 30/70 or even 20/80. Underestimating verification leads to late bug discoveries, schedule slips, and potential silicon respins costing millions.
Best Practice: Plan for 2-3x more verification effort than design. Hire experienced verification engineers, invest in verification infrastructure (UVM, formal tools, emulation), and track coverage metrics weekly.
Mistake #2: Unclear or Incomplete Specifications
Why it's problematic: Ambiguous specs lead to design-verification mismatches where the design implements one interpretation and verification tests a different interpretation. The bug is only caught late in the cycle (or post-silicon), causing expensive rework.
Best Practice: Invest 4-8 weeks in specification review with all stakeholders (architecture, design, verification, software). Use formal specification languages (e.g., PSS - Portable Stimulus Standard) and create reference models before RTL coding starts.
Mistake #3: Ignoring Synthesis Timing Early
// Wrong: Long combinational path that won't meet timing
always @(*) begin
    sum = a + b + c + d + e + f + g + h; // 8-input adder tree
    result = (sum > threshold) ? sum : 0; // Plus comparison and mux
end

// Correct: Pipeline the operation to meet timing
always @(posedge clk) begin
    // Stage 1: Partial sums
    partial1 <= a + b + c + d;
    partial2 <= e + f + g + h;
    threshold_reg <= threshold;

    // Stage 2: Compute final sum and comparison using Stage 1 outputs
    result <= (partial1 + partial2 > threshold_reg) ? (partial1 + partial2) : 0;
end
Why it's problematic: Writing RTL without considering synthesis timing leads to critical path violations discovered late in synthesis. Fixing timing issues requires RTL restructuring (adding pipeline stages), which can break verification and delay the schedule.
Best Practice: Run early synthesis experiments ("quick synthesis") during RTL development to identify timing bottlenecks. Design with target clock frequency in mind--know the typical gate delays for your technology node and structure RTL to meet timing from the start.
Mistake #4: Not Planning for Clock Domain Crossing (CDC)
Why it's problematic: Signals crossing from one clock domain to another can cause metastability--the receiving flip-flop samples during the setup/hold window and enters an unstable state. CDC bugs are notoriously difficult to debug and can cause intermittent failures in silicon.
Best Practice: Use proven CDC synchronizers (two-flip-flop synchronizers for single-bit signals, async FIFOs for multi-bit data). Run CDC analysis tools (Synopsys SpyGlass CDC, Cadence JasperGold CDC) to identify all clock crossings and verify proper synchronization.
Practice Exercise
Challenge: Design Flow Decision Tree
You're leading a project to develop a custom AI accelerator ASIC for edge devices (inference only, not training). Answer the following design flow questions with justification:
Scenario:
- Target: 5nm process node, 100mm² die size
- Performance: 10 TOPS (Tera Operations Per Second) INT8 inference
- Power: 2W TDP for mobile deployment
- Time to market: 18 months from project kickoff
Questions:
- IP Reuse: Should you design the matrix multiply engine from scratch or license existing IP? Consider development time vs. cost.
- Verification Strategy: Given the 18-month timeline, how would you split effort between simulation, formal verification, and emulation?
- Clock Domains: Would you use a single clock domain or multiple clock domains? What are the tradeoffs?
- Synthesis Target: At what stage would you start synthesis experiments--after complete RTL or incrementally during development?
Hint
Consider: (1) NRE costs vs. IP licensing fees and time-to-market impact, (2) Verification pyramid (simulation at base, formal/emulation at top), (3) Power vs. timing complexity tradeoffs, (4) Early feedback vs. design maturity tradeoffs.
Solution
Question 1: IP Reuse Strategy
Answer: License existing IP for matrix multiply engines.
Justification:
- Time-to-market: Developing optimized matrix multiply from scratch requires 6-9 months for a small team. Licensing IP (e.g., Arm Ethos-U, Synopsys DesignWare) provides proven RTL in weeks.
- PPA optimization: Commercial IP vendors have already optimized for 5nm process (performance, power, area). Achieving similar results in-house requires process expertise.
- Verification: Licensed IP comes with comprehensive testbenches and proven coverage, reducing verification burden.
- Cost tradeoff: IP licensing fees ($500K-$2M) are lower than internal development cost (5-10 engineers x 9 months) and the risk of missing the 18-month deadline.
- Focus resources: Allocate scarce engineering resources to differentiating features (custom activation functions, memory hierarchy, power management) rather than commodity IP.
Question 2: Verification Strategy
Answer: 60% simulation, 25% formal verification, 15% emulation.
Justification:
- Simulation (60%): UVM testbenches with constrained-random stimulus cover broad functionality. Target 95% code coverage and 90% functional coverage. Budget 10 months for testbench development and regression.
- Formal Verification (25%): Use formal tools for:
- Control logic and FSM verification (prove all states reachable, no deadlocks)
- Interface protocol compliance (AXI, APB checkers)
- CDC verification (all clock crossings properly synchronized)
- Formal takes 3-4 months but finds corner cases missed by simulation
- Emulation (15%): FPGA-based emulation or hardware emulation platform (Palladium, Veloce) for:
- Running real AI models (ResNet, MobileNet) at 100K-1M cycles/sec
- Software bring-up and driver development in parallel with RTL development
- Power analysis with real workloads
- Budget 2-3 months for emulation bring-up and runs
- Why this split: Simulation provides breadth, formal provides depth (exhaustive proofs), emulation provides reality (real software on real design). The 18-month timeline requires parallel verification approaches.
Question 3: Clock Domains
Answer: Use 3-4 clock domains: core compute, memory interface, low-speed peripherals, and optional power-saving domain.
Justification:
- Core compute domain (800-1000 MHz): Matrix engines and activation functions run at high frequency for performance
- Memory interface domain (DDR frequency, e.g., 2133 MHz DDR5): Separate domain allows independent frequency scaling and matches DRAM interface requirements
- Low-speed peripherals (100-200 MHz): Configuration registers, interrupts, debug logic don't need high speed; running slower saves power
- Optional power domain (400-600 MHz): Intermediate frequency for mid-tier compute blocks during DVFS (Dynamic Voltage Frequency Scaling)
- Tradeoffs:
- Pro: Multiple domains enable DVFS for 2W power budget--scale down non-critical domains during low activity
- Pro: Isolation prevents high-speed noise from affecting sensitive analog (if present)
- Con: CDC complexity--need async FIFOs, synchronizers, and CDC verification
- Con: Synthesis and timing closure more complex with multiple clocks
- Why not single domain: Single clock at 1GHz would prevent power scaling (all blocks run fast always) and waste power in peripherals. Meeting 2W TDP requires fine-grained power management only achievable with multiple domains.
Question 4: Synthesis Timing
Answer: Start synthesis experiments after the first functional block is complete (~month 3), then run incremental synthesis every 2-4 weeks.
Justification:
- Early synthesis (month 3): Synthesize the matrix multiply engine (largest block) to:
- Validate timing feasibility at 5nm process with target frequency (800-1000 MHz)
- Get area estimates to validate 100mm² die budget
- Identify critical paths early before architecture is locked
- Learn technology library characteristics (gate delays, routing congestion)
- Incremental synthesis (every 2-4 weeks):
- As each block reaches functional stability, add to synthesis runs
- Track PPA trends: is area growing too fast? Are new critical paths appearing?
- Catch synthesis issues early when RTL refactoring is easier
- Build synthesis scripts and constraint (SDC) files incrementally
- Full-chip synthesis (month 12): Once all RTL is functionally complete, run full-chip synthesis for final area/timing validation before physical design
- Why not wait: Waiting until month 12 to run first synthesis is extremely risky. If timing violations appear, RTL changes could require verification rework, potentially breaking the 18-month schedule. Early synthesis provides risk mitigation.
- Why not too early: Synthesizing before RTL is functionally stable wastes time--synthesis results change with every RTL update. Wait for functional maturity (passes basic tests) before investing in synthesis tuning.
Real-World Application: This decision tree mirrors actual practices at companies like NVIDIA developing AI accelerators. For example, NVIDIA's tensor cores in H100 GPU were developed with extensive IP reuse (Arm interconnects, standard memory controllers), heavy verification investment (formal for control paths, emulation for MLPerf workloads), multiple clock domains for power efficiency, and iterative synthesis starting mid-project to catch timing issues before physical design.
Summary
In this tutorial, you learned:
- ASIC design flow progresses through three stages: (1) Specification and Architecture, (2) Implementation and Verification, and (3) Fabrication and Validation
- RTL design using Verilog/SystemVerilog describes circuit behavior at register-transfer level, which synthesis tools convert to gate-level netlists mapped to standard cell libraries
- Verification consumes 60-70% of project effort, using simulation, formal methods, and emulation to achieve functional coverage before tape-out
- Physical design (Place and Route) transforms the netlist into GDSII layout, managing timing closure, power delivery, and design rule compliance
- Post-silicon validation tests fabricated chips with limited visibility; bugs found at this stage are extremely expensive, emphasizing the importance of thorough pre-silicon verification