
A Verilog full adder is a combinational circuit that adds three 1-bit inputs (a, b and a carry-in cin) and produces a sum and a carry-out cout.
Chained together, full adders form the N-bit adders at the core of every ALU. The quickest way to describe one in Verilog is a single continuous assignment:
// 1-bit full adder in one line: {carry, sum} = a + b + cin
assign {cout, sum} = a + b + cin;
10 min read | Beginner Level
What You'll Learn
- Derive the full adder's sum and carry equations from its truth table
- Model a full adder in gate-level, dataflow and behavioral Verilog
- Build a 4-bit ripple-carry adder by instantiating 1-bit full adders
- Understand what each style synthesizes into and why carry propagation limits speed
Truth Table
A full adder adds three bits, so the result ranges from 0 to 3 and needs two output bits. sum is the LSB and cout is the MSB.
Put another way, {cout, sum} is the 2-bit count of how many inputs are 1.
| A | B | Cin | Cout | Sum |
|---|---|---|---|---|
| 0 | 0 | 0 | 0 | 0 |
| 0 | 0 | 1 | 0 | 1 |
| 0 | 1 | 0 | 0 | 1 |
| 0 | 1 | 1 | 1 | 0 |
| 1 | 0 | 0 | 0 | 1 |
| 1 | 0 | 1 | 1 | 0 |
| 1 | 1 | 0 | 1 | 0 |
| 1 | 1 | 1 | 1 | 1 |
Full Adder Equations
Solving the K-maps for the truth table gives two Boolean equations:
sum  = a ^ b ^ cin                  // 1 when an odd number of inputs are 1
cout = (a & b) | (cin & (a ^ b))    // 1 when at least two inputs are 1
sum is a 3-input XOR (odd parity). cout is a majority function.
The carry is often written as (a & b) | (b & cin) | (a & cin). The form above is preferred because it reuses the a ^ b term that the sum already needs.
a & b is the generate signal (this bit creates a carry on its own). a ^ b is the propagate signal (this bit passes an incoming carry through). Faster adders such as carry-lookahead are built from these two terms.
Quick Check
Q: If cin is tied to 0, what do the equations reduce to, and what circuit is left?
Show Answer
sum = a ^ b and cout = a & b, which is a half adder. Synthesis performs this simplification automatically when cin is a constant 0.
Design
A full adder is purely combinational, so it can be written in three common Verilog styles. All three describe the same hardware.
1. Gate-Level Model
The gate-level style wires together Verilog's built-in gate primitives. It maps one-to-one onto a schematic.
// 1-bit full adder built from gate primitives
module full_adder_gate (
  input  a,      // First operand bit
  input  b,      // Second operand bit
  input  cin,    // Carry in from the less significant stage
  output sum,    // Sum bit
  output cout    // Carry out to the more significant stage
);

  wire p;        // Propagate: a ^ b
  wire g;        // Generate:  a & b
  wire t;        // Carry passed through this stage: cin & p

  xor x1 (p,    a, b);     // p    = a ^ b
  xor x2 (sum,  p, cin);   // sum  = a ^ b ^ cin
  and a1 (g,    a, b);     // g    = a & b
  and a2 (t,    p, cin);   // t    = (a ^ b) & cin
  or  o1 (cout, g, t);     // cout = generated OR propagated carry

endmodule
2. Dataflow Model (assign)
The dataflow style writes the equations directly with continuous assignments. Use it when you want the bit-level logic to be visible in the code.
// 1-bit full adder using Boolean equations
module full_adder (
  input  a,
  input  b,
  input  cin,
  output sum,
  output cout
);

  // Sum is the XOR (odd parity) of all three inputs
  assign sum  = a ^ b ^ cin;

  // Carry: this bit generates one (a & b),
  // or it propagates the incoming carry (cin & (a ^ b))
  assign cout = (a & b) | (cin & (a ^ b));

endmodule
3. Behavioral Model (+ operator)
The behavioral style uses the arithmetic operator +. Concatenation packs both results so the carry lands in the MSB.
// 1-bit full adder using the + operator
module full_adder_beh (
  input  a,
  input  b,
  input  cin,
  output sum,
  output cout
);

  // {cout, sum} is 2 bits wide, so the addition is evaluated
  // at 2 bits and the carry is kept in cout
  assign {cout, sum} = a + b + cin;

endmodule
How a 1-bit Full Adder Synthesizes
All three models synthesize to the same logic: XOR gates for the sum and an AND-OR (majority) structure for the carry.
Synthesis optimizes the Boolean function, not the coding style. The gate-level version does not produce "better" hardware.
| Output | Logic Function | Typical Synthesized Hardware |
|---|---|---|
sum | 3-input XOR | Two 2-input XOR gates (or one XOR3 cell) |
cout | 3-input majority | AND-OR or AOI gates (or one MAJ3 cell) |
| Both (ASIC) | Full adder | Often a single dedicated full-adder standard cell |
| Both (FPGA) | Full adder | LUT plus dedicated carry-chain logic |
Quick Check
Q: Will full_adder_gate and full_adder_beh give different gate counts after synthesis?
Show Answer
No. Both describe the same Boolean function, and synthesis optimizes the function rather than the way it was written. The choice of style is about readability.
4-bit Ripple-Carry Adder
To add multi-bit numbers, connect the cout of each full adder to the cin of the next more significant stage. The carry "ripples" from bit 0 up to bit 3.
Plan:
c[0] = cin                                 // external carry enters bit 0
for i = 0 to 3:
    sum[i], c[i+1] = FULL_ADD(a[i], b[i], c[i])
cout = c[4]                                // carry out of bit 3 leaves the adder
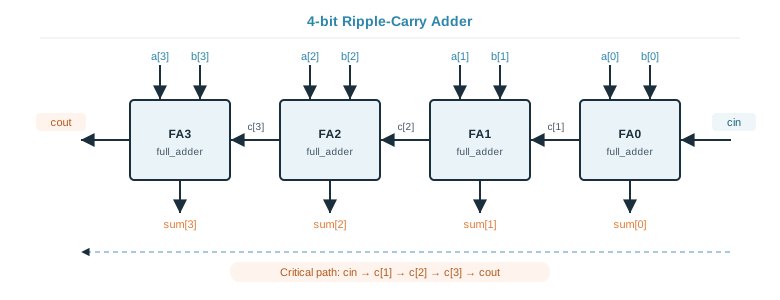
// 4-bit ripple-carry adder built from four 1-bit full adders
module rca_4bit (
  input  [3:0] a,      // 4-bit operand A
  input  [3:0] b,      // 4-bit operand B
  input        cin,    // Carry in to bit 0
  output [3:0] sum,    // 4-bit sum
  output       cout    // Carry out of bit 3
);

  // Internal carries between stages:
  // c[1] = carry out of bit 0 ... c[3] = carry out of bit 2
  wire [3:1] c;

  // Bit 0 receives the external carry in
  full_adder fa0 (.a(a[0]), .b(b[0]), .cin(cin ), .sum(sum[0]), .cout(c[1]));

  // Each stage takes the carry from the stage below it
  full_adder fa1 (.a(a[1]), .b(b[1]), .cin(c[1]), .sum(sum[1]), .cout(c[2]));
  full_adder fa2 (.a(a[2]), .b(b[2]), .cin(c[2]), .sum(sum[2]), .cout(c[3]));

  // The last stage drives the external carry out
  full_adder fa3 (.a(a[3]), .b(b[3]), .cin(c[3]), .sum(sum[3]), .cout(cout));

endmodule
For wider adders, use a generate block with a for loop to create N full adders instead of writing each instance by hand.
Why Ripple-Carry Is Slow
The MSB sum cannot settle until the carry has passed through every lower stage.
Each stage adds about two gate delays to the carry path, so the worst-case delay grows linearly with width.
PPA Impact: Ripple-carry has the smallest area (N full adders, nothing else) but the longest critical path. A 32-bit ripple-carry chain is about 8 times longer than a 4-bit one, which can limit the clock frequency of the whole design.
Where Are Full Adders Used?
Full adders form the integer ALU in every CPU and microcontroller. They also appear wherever a value is counted or offset: program counter increments, load/store address generation and DMA loop counters. Low-power microcontrollers often accept ripple-carry adders for their small area, while high-frequency processors use faster carry structures built from the same equations.
4-bit Adder Using the + Operator
In practice, RTL designers rarely instantiate full adders by hand. The same 4-bit adder fits in one line with the + operator.
It can be written with a continuous assignment using assign, or with an always block that is sensitive to all inputs.
// 4-bit adder with carry in and carry out, using a continuous assignment
module fulladd (  input [3:0] a,       // 4-bit operand A
                  input [3:0] b,       // 4-bit operand B
                  input c_in,          // Carry in
                  output c_out,        // Carry out (bit 4 of the result)
                  output [3:0] sum);   // Lower 4 bits of the result

   // The LHS is 5 bits wide, so the addition is evaluated at 5 bits
   // and the carry is captured in c_out
   assign {c_out, sum} = a + b + c_in;
endmodule
The version below uses an always block that runs whenever any input changes.
Outputs assigned inside an always block must be declared reg, but this is still combinational logic. No flip-flops are created.
// Same 4-bit adder modeled with an always block
module fulladd (  input [3:0] a,
                  input [3:0] b,
                  input c_in,
                  output reg c_out,      // 'reg' is required for procedural assignment
                  output reg [3:0] sum);

  // @(*) automatically includes a, b and c_in in the sensitivity list
  always @ (*) begin
    {c_out, sum} = a + b + c_in;   // Blocking assignment for combinational logic
  end
endmodule
What the + Operator Synthesizes Into
For a + b + c_in, synthesis infers an adder from its arithmetic library instead of building one from your gates. It then picks the architecture that meets your timing constraints:
- Relaxed timing: a ripple-carry adder, the same as
rca_4bit(smallest area) - Tight timing: a carry-lookahead or parallel-prefix adder (more area, shorter critical path)
- FPGA targets: the dedicated hardware carry chain in each logic block
The c_in term does not create a second adder. It feeds straight into the carry input of bit 0.
Prefer the + operator for multi-bit arithmetic in RTL. It is easier to read, scales to any width with parameters, and lets synthesis choose the best adder for your timing target.
Quick Check
Q: What is the largest value a + b + c_in can produce for 4-bit a and b? Are 5 bits always enough?
Show Answer
15 + 15 + 1 = 31, which is 5'b11111, so the 5-bit {c_out, sum} always fits. Adding two N-bit numbers plus a carry in needs exactly N+1 bits.
Hardware Schematic
The synthesized 4-bit adder with carry in and carry out is shown below.

Adders in Signal Processing
Digital filters, audio codecs and image pipelines spend most of their logic on multiply-accumulate operations, and every accumulate step is a wide adder. Designers add extra carry bits (guard bits) so that summing many samples never overflows, just as c_out extends a 4-bit sum to 5 bits.
Testbench
Random Stimulus Testbench
This testbench drives random values into the 4-bit fulladd module and prints the result with $monitor.
module tb_fulladd;
  // 1. Declare testbench variables
  reg [3:0] a;
  reg [3:0] b;
  reg c_in;
  wire c_out;
  wire [3:0] sum;
  integer i;

  // 2. Instantiate the design and connect to testbench variables
  fulladd  fa0 ( .a (a),
                 .b (b),
                 .c_in (c_in),
                 .c_out (c_out),
                 .sum (sum));

  // 3. Provide stimulus to test the design
  initial begin
    a <= 0;
    b <= 0;
    c_in <= 0;

    // Print all signals whenever any of them change
    $monitor ("a=0x%0h b=0x%0h c_in=0x%0h c_out=0x%0h sum=0x%0h", a, b, c_in, c_out, sum);

    // Apply random values to the inputs every 10 time units
    for (i = 0; i < 5; i = i+1) begin
      #10 a <= $random;
          b <= $random;
          c_in <= $random;   // $random is truncated to 1 bit for c_in
    end
  end
endmodule
When a + b + c_in exceeds 15, sum wraps around and keeps only the lower 4 bits, while bit 4 goes to c_out.
For example, the third line of the output shows 0x3 + 0xd + 0x1 = 0x11, so sum = 0x1 and c_out = 1.
Simulation Log
ncsim> run
a=0x0 b=0x0 c_in=0x0 c_out=0x0 sum=0x0
a=0x4 b=0x1 c_in=0x1 c_out=0x0 sum=0x6
a=0x3 b=0xd c_in=0x1 c_out=0x1 sum=0x1
a=0x5 b=0x2 c_in=0x1 c_out=0x0 sum=0x8
a=0xd b=0x6 c_in=0x1 c_out=0x1 sum=0x4
a=0xd b=0xc c_in=0x1 c_out=0x1 sum=0xa
ncsim: *W,RNQUIE: Simulation is complete.
Exhaustive Self-Checking Testbench
A 4-bit adder with a carry in has only 29 = 512 input combinations, so you can test every one and compare it against an expected value.
Plan:
for every 9-bit value i from 0 to 511:
    {cin, a, b} = i
    wait for logic to settle
    if {cout, sum} != a + b + cin (computed at 5 bits): report error
print PASS if no errors, else FAIL with the error count
module tb_rca_4bit;
  reg  [3:0] a, b;
  reg        cin;
  wire [3:0] sum;
  wire       cout;
  integer    i, errors;

  // Design under test: the ripple-carry adder built from full adders
  rca_4bit dut (.a(a), .b(b), .cin(cin), .sum(sum), .cout(cout));

  initial begin
    errors = 0;

    // Walk through all 512 combinations of {cin, a, b}
    for (i = 0; i < 512; i = i + 1) begin
      {cin, a, b} = i;   // Unpack the loop counter into the 9 input bits
      #1;                // Let the combinational logic settle

      // Compare against a 5-bit behavioral reference.
      // {1'b0, a} widens the expression so the carry is kept even
      // inside $display, where expression widths are self-determined
      if ({cout, sum} !== {1'b0, a} + b + cin) begin
        $display("ERROR: a=%0d b=%0d cin=%0d -> got %0d, expected %0d",
                 a, b, cin, {cout, sum}, {1'b0, a} + b + cin);
        errors = errors + 1;
      end
    end

    if (errors == 0) $display("PASS: all 512 combinations correct");
    else             $display("FAIL: %0d mismatches", errors);
    $finish;
  end
endmodule
Using !== instead of != also fails on x or z values, which catches unconnected carry wires that a plain comparison would miss.
Adders in Networking Hardware
Network interface controllers verify packets with checksums computed by one's-complement addition. In that scheme, the carry out of the MSB is added back into the LSB. This "end-around carry" is a direct reuse of the full adder's carry out and carry in ports.
Common Beginner Mistakes
Mistake #1: Losing the carry because of expression width
Verilog sizes an expression using the widest operand and the left-hand side. If the LHS is narrow, the carry is dropped before you can use it, and simulation gives no warning.
// WRONG: every term is at most 4 bits and the LHS is 1 bit,
// so the sum is computed in 4 bits, the carry is lost,
// and shifting right by 4 always gives 0
assign c_out = (a + b + c_in) >> 4;

// RIGHT: a 5-bit LHS makes the addition 5 bits wide
assign {c_out, sum} = a + b + c_in;
Mistake #2: Reversing the concatenation order
The leftmost item in a concatenation is the most significant. The carry is bit 4 of the result, so it must be listed first.
// WRONG: puts the carry in bit 0 and the sum in bits 4:1
assign {sum, c_out} = a + b + c_in;

// RIGHT: the MSB (carry) comes first
assign {c_out, sum} = a + b + c_in;
Mistake #3: Incomplete sensitivity list in an always-based adder
Synthesis ignores the sensitivity list and builds a correct adder, but the simulator only re-evaluates the block on the listed signals. Simulation then passes while the real hardware behaves differently, which is a simulation-synthesis mismatch.
// WRONG: c_in is missing, so simulation does not update
// sum when only the carry input changes
always @ (a or b)
  {c_out, sum} = a + b + c_in;

// RIGHT: @(*) includes every signal read inside the block
always @ (*)
  {c_out, sum} = a + b + c_in;
Mistake #4: Broken carry chain from a misspelled wire
An undeclared name in a port connection silently creates a new 1-bit implicit net. The next stage then reads an undriven carry (z), and every sum bit above it becomes x.
// WRONG: c_1 is never declared (the declared wire is c[1]),
// so fa1 receives an undriven carry and sum[3:1] become x
full_adder fa0 (.a(a[0]), .b(b[0]), .cin(cin),  .sum(sum[0]), .cout(c_1));
full_adder fa1 (.a(a[1]), .b(b[1]), .cin(c[1]), .sum(sum[1]), .cout(c[2]));

// RIGHT: use the declared carry vector consistently
full_adder fa0 (.a(a[0]), .b(b[0]), .cin(cin),  .sum(sum[0]), .cout(c[1]));
Add `default_nettype none at the top of your design files. Undeclared names then cause a compile error instead of a floating wire in your carry chain.
Practice Exercise
Challenge 1: Build an 8-bit Adder from Two 4-bit Adders
Create a module rca_8bit with 8-bit inputs a and b, a carry in cin, an 8-bit sum and a carry out cout. Build it from two instances of rca_4bit.
Hint
The lower adder handles bits [3:0] and receives cin. Its carry out becomes the carry in of the upper adder, which handles bits [7:4].
Solution
module rca_8bit (
  input  [7:0] a,
  input  [7:0] b,
  input        cin,
  output [7:0] sum,
  output       cout
);

  wire c4;   // Carry from the lower nibble into the upper nibble

  // Lower nibble: bits 3:0
  rca_4bit lo (.a(a[3:0]), .b(b[3:0]), .cin(cin), .sum(sum[3:0]), .cout(c4));

  // Upper nibble: bits 7:4, fed by the carry out of the lower nibble
  rca_4bit hi (.a(a[7:4]), .b(b[7:4]), .cin(c4),  .sum(sum[7:4]), .cout(cout));

endmodule
This is still a ripple-carry adder. The carry now passes through 8 full adders, so the critical path is twice as long as in the 4-bit version.
Challenge 2: Turn the Adder into an Adder/Subtractor
Add a control input sub that selects a + b (sub = 0) or a - b (sub = 1). Reuse the adder's carry in instead of building a separate subtractor.
Hint
In two's complement, a - b = a + ~b + 1. XOR each bit of b with sub to invert it conditionally, and use sub as the carry in to supply the +1.
Solution
module add_sub_4bit (
  input  [3:0] a,
  input  [3:0] b,
  input        sub,    // 0 = add, 1 = subtract
  output [3:0] result,
  output       cout    // For subtraction, cout = 1 means no borrow (a >= b)
);

  // XOR with {4{sub}} inverts b only when subtracting
  wire [3:0] b_mod = b ^ {4{sub}};

  // sub doubles as the carry in, providing the +1 for two's complement
  rca_4bit u_add (.a(a), .b(b_mod), .cin(sub), .sum(result), .cout(cout));

endmodule
The only added hardware is four XOR gates. This is how a basic ALU shares one adder for both addition and subtraction.
Summary
In this tutorial, you learned:
- A full adder computes
sum = a ^ b ^ cin, andcoutis the majority of the three inputs - Gate-level, dataflow and behavioral full adders synthesize to the same XOR and AND-OR logic
- A ripple-carry adder chains each
coutinto the nextcin; it is small, but its delay grows linearly with width - The
+operator lets synthesis infer an adder and choose ripple, lookahead or an FPGA carry chain to meet timing - An N-bit addition with carry in needs N+1 result bits; write
{c_out, sum}with the carry first - Exhaustive self-checking testbenches are practical for small adders and catch broken carry chains
