
The UVM resource database is the global store underneath all of UVM's configuration. It holds resources - typed values with a name and a scope - in a single pool that any part of the testbench can write to and read from. You access it through uvm_resource_db, or more often through uvm_config_db, which is a component-friendly layer built on top of it.
Most testbench code only ever touches uvm_config_db. Knowing how the resource database works underneath explains why a lookup finds the value it does, and gives you a tool for sharing data that has nothing to do with the component hierarchy, such as settings for register models or sequences.
7 min read | Intermediate Level
What You'll Learn
- Describe what a resource is and the fields it carries
- Explain how the resource pool stores and looks up resources
- Use the main
uvm_resource_dbmethods to set and read values - Decide when to use
uvm_resource_dbrather thanuvm_config_db
What is a Resource?
A resource is a parameterized container, uvm_resource #(T), that holds one value of any type: an int, a string, a virtual interface or a class handle. Each resource carries a few fields that decide who can find it.
| Field | Meaning |
|---|---|
| Name | The string the resource is stored under. A name lookup must supply the same name. |
| Value | The data itself. |
| Type | The type parameter T. Lookups are type-safe, so a request for an int never returns a string. |
| Scope | A pattern describing the set of scopes where the resource is visible, for example "*" or "uvm_test_top.m_env.*". |
| Precedence | A number that breaks ties when several resources match. New resources start at the default, 1000. |
How the Resource Pool Works
All resources live in one singleton, uvm_resource_pool. The pool keeps two associative arrays: one keyed by name and one keyed by type. Each entry holds a queue of resources, so one resource appears both in the queue for its name and in the queue for its type.
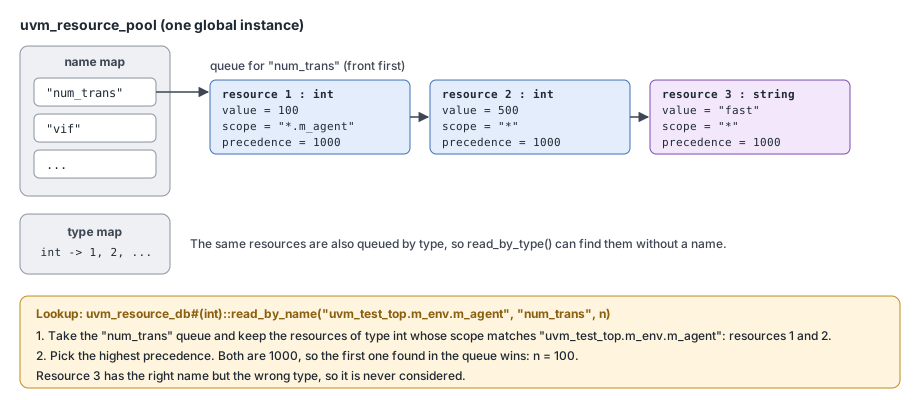
A lookup takes the queue for the requested name or type, keeps only the resources of the right type whose scope matches the requested scope, and returns the one with the highest precedence. When two matching resources have the same precedence, the first one found in the queue wins. Because a normal set() adds new resources at the back of the queue, an earlier uvm_resource_db setting beats a later one with the same name and scope.
The pool also records every lookup, both successful and failed. Dumping that history at the end of a run shows which resources were found, which were not, and which components asked for them, which is very useful when a value goes missing.
Quick Check
Q: Two resources named "mode", both of type int and both with scope "*", are set one after the other with uvm_resource_db. Which value does read_by_name() return?
Show Answer
The first one. Both match and both have the default precedence, so the tie goes to the resource found first in the queue, which is the one set earlier.
Syntax: uvm_resource_db
Like uvm_config_db, every method is static and the type is the class parameter. The scope is a plain string rather than a component plus a relative path.
uvm_resource_db #(T)::set          (string scope, string name, T val, uvm_object accessor = null);
uvm_resource_db #(T)::read_by_name (string scope, string name, inout T val, uvm_object accessor = null); // bit
uvm_resource_db #(T)::read_by_type (string scope, inout T val, uvm_object accessor = null);              // bit
uvm_resource_db #(T)::write_by_name(string scope, string name, T val, uvm_object accessor = null);       // bit
uvm_resource_db #(T)::dump ();                                                                         // print the pool
scopeinset()is the visibility pattern stored with the resource. In the read methods it is the scope you are looking up from.accessoris optional and used only for the audit record. Passingthismakes the lookup history show who set or read the value.- The read methods return 1 on success and 0 if nothing matched, leaving
valunchanged.
Example: Sharing a Value
// Test: make a setting visible everywhere
uvm_resource_db #(int)::set("*", "num_trans", 500, this);

// A sequence: read it from its own scope; keep the default if it is missing
int num_trans = 100;
if (!uvm_resource_db #(int)::read_by_name(get_full_name(), "num_trans", num_trans, this))
  `uvm_info("RSRC", "num_trans not set, using 100", UVM_LOW)
Sequences are a natural fit for uvm_resource_db, because a sequence is not a component and has no fixed place in the hierarchy. Reading with get_full_name(), which for a running sequence includes the sequencer's path, keeps the lookup scoped to where the sequence actually runs.
Example: Disabling Register Tests
The built-in register sequences check the resource database for bit-type resources named NO_REG_TESTS in a special "REG::" namespace. Setting one that matches a register block's full name makes those sequences skip that block.
uvm_resource_db #(bit)::set({"REG::", regmodel.blk.get_full_name(), ".*"}, "NO_REG_TESTS", 1, this);
The scope here is the register block's name, not a component path, which is exactly the kind of setting uvm_config_db is not designed for. The ".*" extends the setting to every register inside the block. The built-in sequences are described in UVM Register Model Classes.
Resource DB or Config DB?
uvm_config_db uses the same pool, but it builds the scope for you from a component and a relative path, and it adds rules that suit a component hierarchy. In particular, during the build phase a setting made higher in the hierarchy takes precedence, and settings from the same level follow "last setting wins". Plain uvm_resource_db has no hierarchy rules, so the first matching resource of equal precedence wins.
- Use
uvm_config_dbfor anything aimed at components: virtual interfaces, agent modes, configuration objects. See UVM Config Database. - Use
uvm_resource_dbfor data that is not tied to a component path, such as register-model settings or values read by sequences. - Avoid mixing both APIs for the same name and field. The two have different precedence rules, so mixing them makes it hard to predict which value is found.
Calling uvm_resource_db#(int)::dump(), or running with +UVM_RESOURCE_DB_TRACE, prints the resources in the pool and the lookups made against them. It is the quickest way to see why a value was not found.
Common Mistakes
Mistake #1: Expecting a later uvm_resource_db set() to override an earlier one
With equal precedence the first matching resource in the queue wins, and a normal set() adds to the back. The second set() of the same name and scope is therefore ignored by lookups. The pool provides set_override() for the case where a new resource really must win.
Mistake #2: Reading with the wrong type
A resource set as uvm_resource_db#(int) cannot be read as uvm_resource_db#(bit) or uvm_resource_db#(int unsigned). The lookup filters by type, so it simply reports that nothing was found.
Mistake #3: Using a component-style scope with the REG:: settings
The register sequences look up "REG::" followed by the register's full name in the model. Using uvm_config_db with this as the context prefixes the scope with the component path, so the setting never matches and the block is still tested.
Summary
In this article, you learned:
- A resource is a typed value with a name, a scope and a precedence, stored in the global
uvm_resource_pool - The pool queues each resource by name and by type, and every lookup is recorded for debugging
- A lookup returns the matching resource with the highest precedence, and ties go to the first one found
uvm_resource_dbuses plain string scopes and suits data outside the component hierarchyuvm_config_dbsits on the same pool but adds hierarchy-based precedence for configuring components
